TopHub·Oct 2
Spring AI Modular RAG and TypeSafe Jev: Retrieve More, Keep Only What Answers
Spring AI: RAG Doc | Jev Doc | Demo
In the previous article we introduced Spring AI TypeSafe and its Jev model: typed questions in, calibrated numbers out, in a few hundred milliseconds. One row in that article's SPI table deserves its own post. JevDocumentFilter and JevDocumentReranker are DocumentPostProcessors, which means they plug straight into Spring AI's Modular RAG pipeline.
This article puts the two together. Two LLM calls clean up and multiply the user's question before retrieval. Jev then judges every retrieved chunk before it reaches the prompt. The whole pipeline is one advisor builder.
💡 Demo: The complete example is the
05-1-modular-ragmodule. It sits next to05-rag, the naive version, so you can diff the two. Every output quoted below is from a live run.
Why Naive RAG Falls Short
The classic Spring AI RAG demo is a QuestionAnswerAdvisor over a vector store. It embeds the user's text, fetches similar chunks and stuffs them into the prompt. That works on stage and gets shaky in real life, for three reasons:
Users don't type search queries. They type "I'm a Florida resident and heard a lot about storms last fall. Did Milton actually make landfall in my state, and where?" Embedding that verbatim drags all the noise into the search.
Similar is not the same as useful. A vector store returns chunks that are about the topic. A reference list that mentions "Hurricane Milton" five times scores high and answers nothing.
Retrieved text is untrusted input. Whatever sits in your documents goes straight into the prompt, including text written to hijack the model.
We will answer exactly that question over a Wikipedia PDF about Hurricane Milton, and fix each problem with one pluggable component.
Modular RAG in Spring AI
The RetrievalAugmentationAdvisor, from the spring-ai-rag module, implements the architecture described in Modular RAG: Transforming RAG Systems into LEGO-like Reconfigurable Frameworks. From the outside it is just another advisor: it sits between your prompt and the model, runs the retrieval phases, and appends the result to the user message. The system prompt and the question pass through untouched.
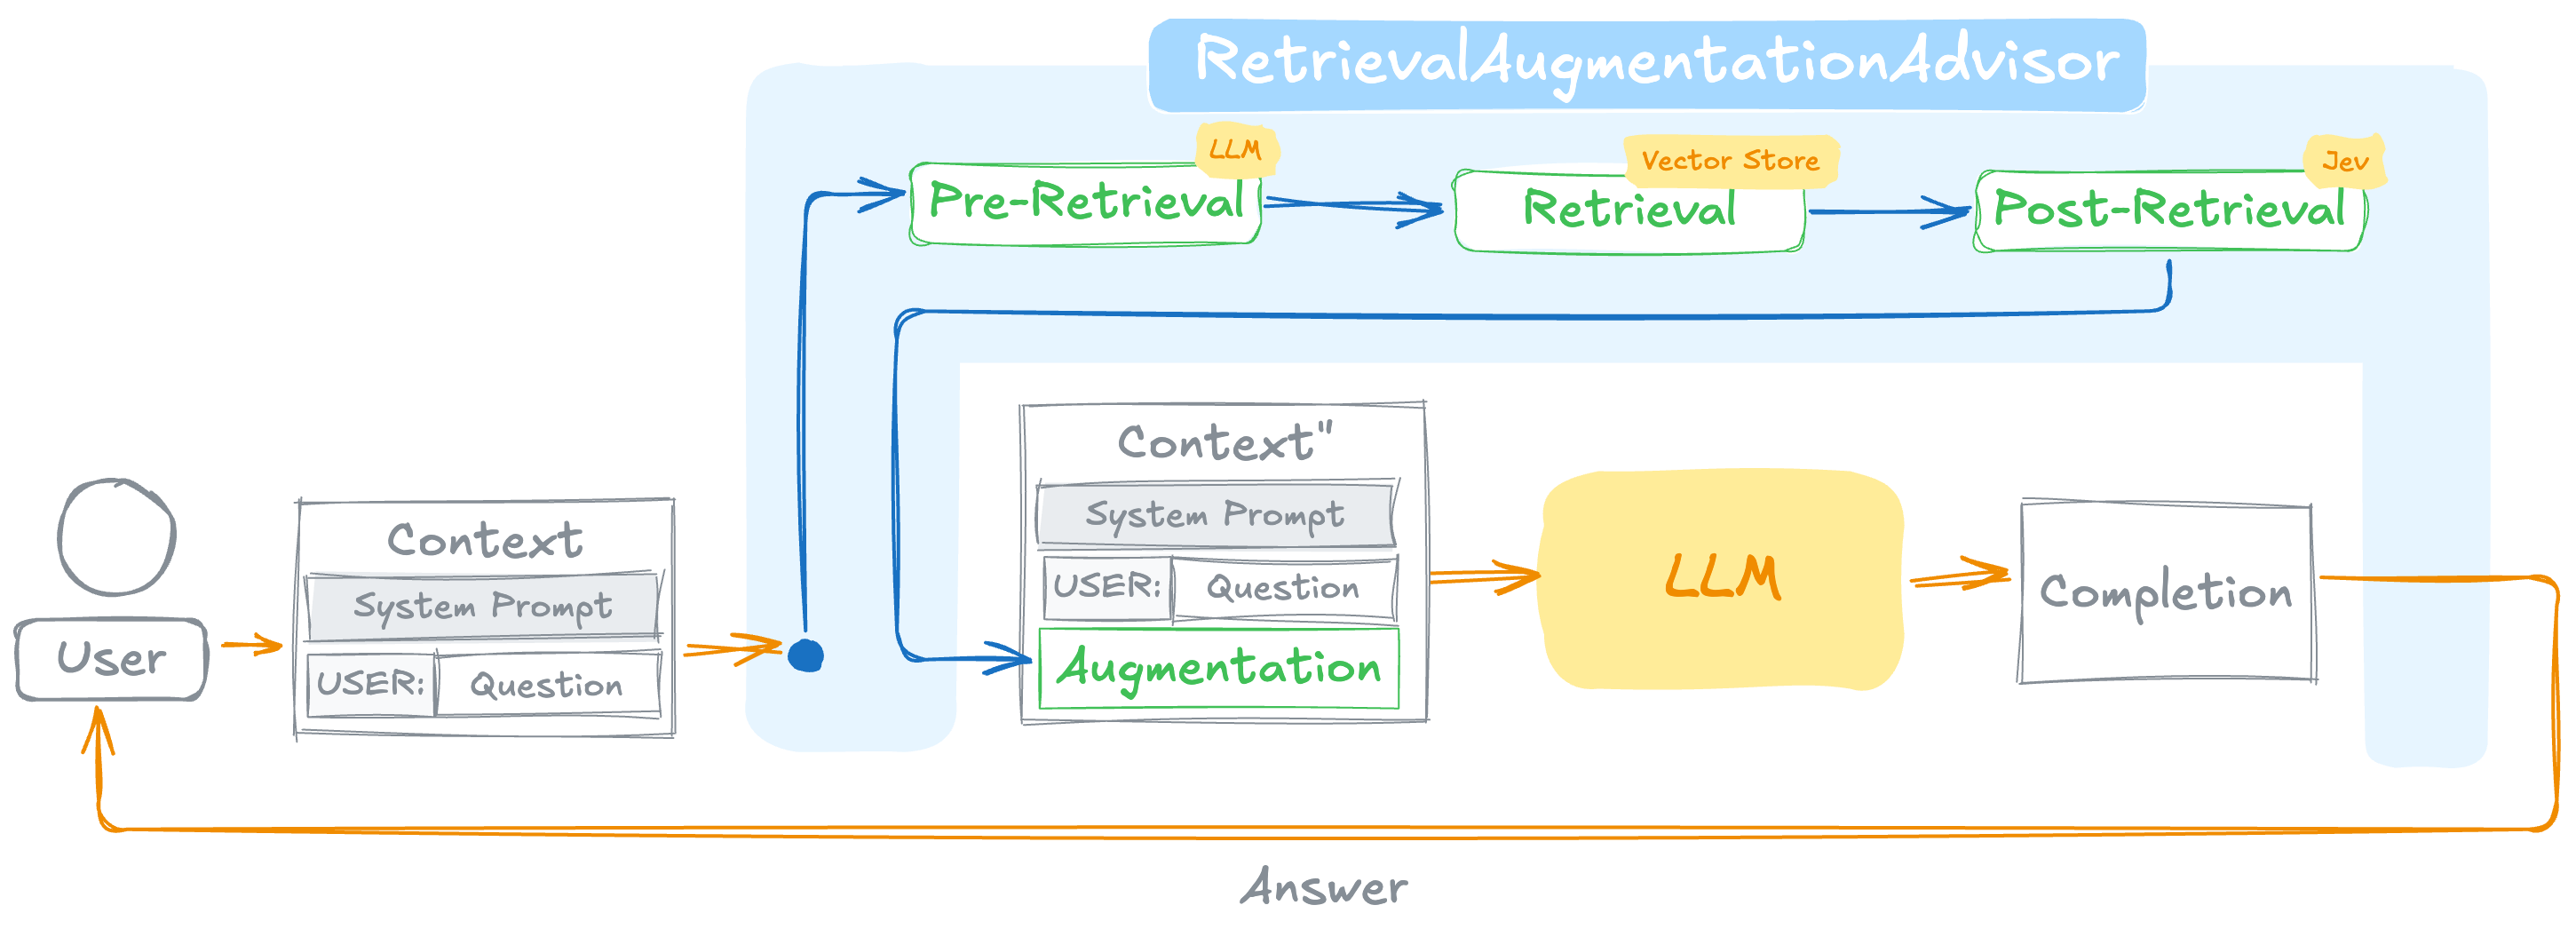
Inside, each phase is a small interface you can swap:
Phase | Spring AI interface | Job | Used in this demo |
|---|---|---|---|
Pre-retrieval |
| rewrite one query into a better one |
|
Pre-retrieval |
| turn one query into several |
|
Retrieval |
| fetch documents for one query |
|
Retrieval |
| merge the results of all queries |
|
Post-retrieval |
| filter, rerank or compress documents |
|
Generation |
| put context and question into the prompt |
|
Here is the full flow for one call:
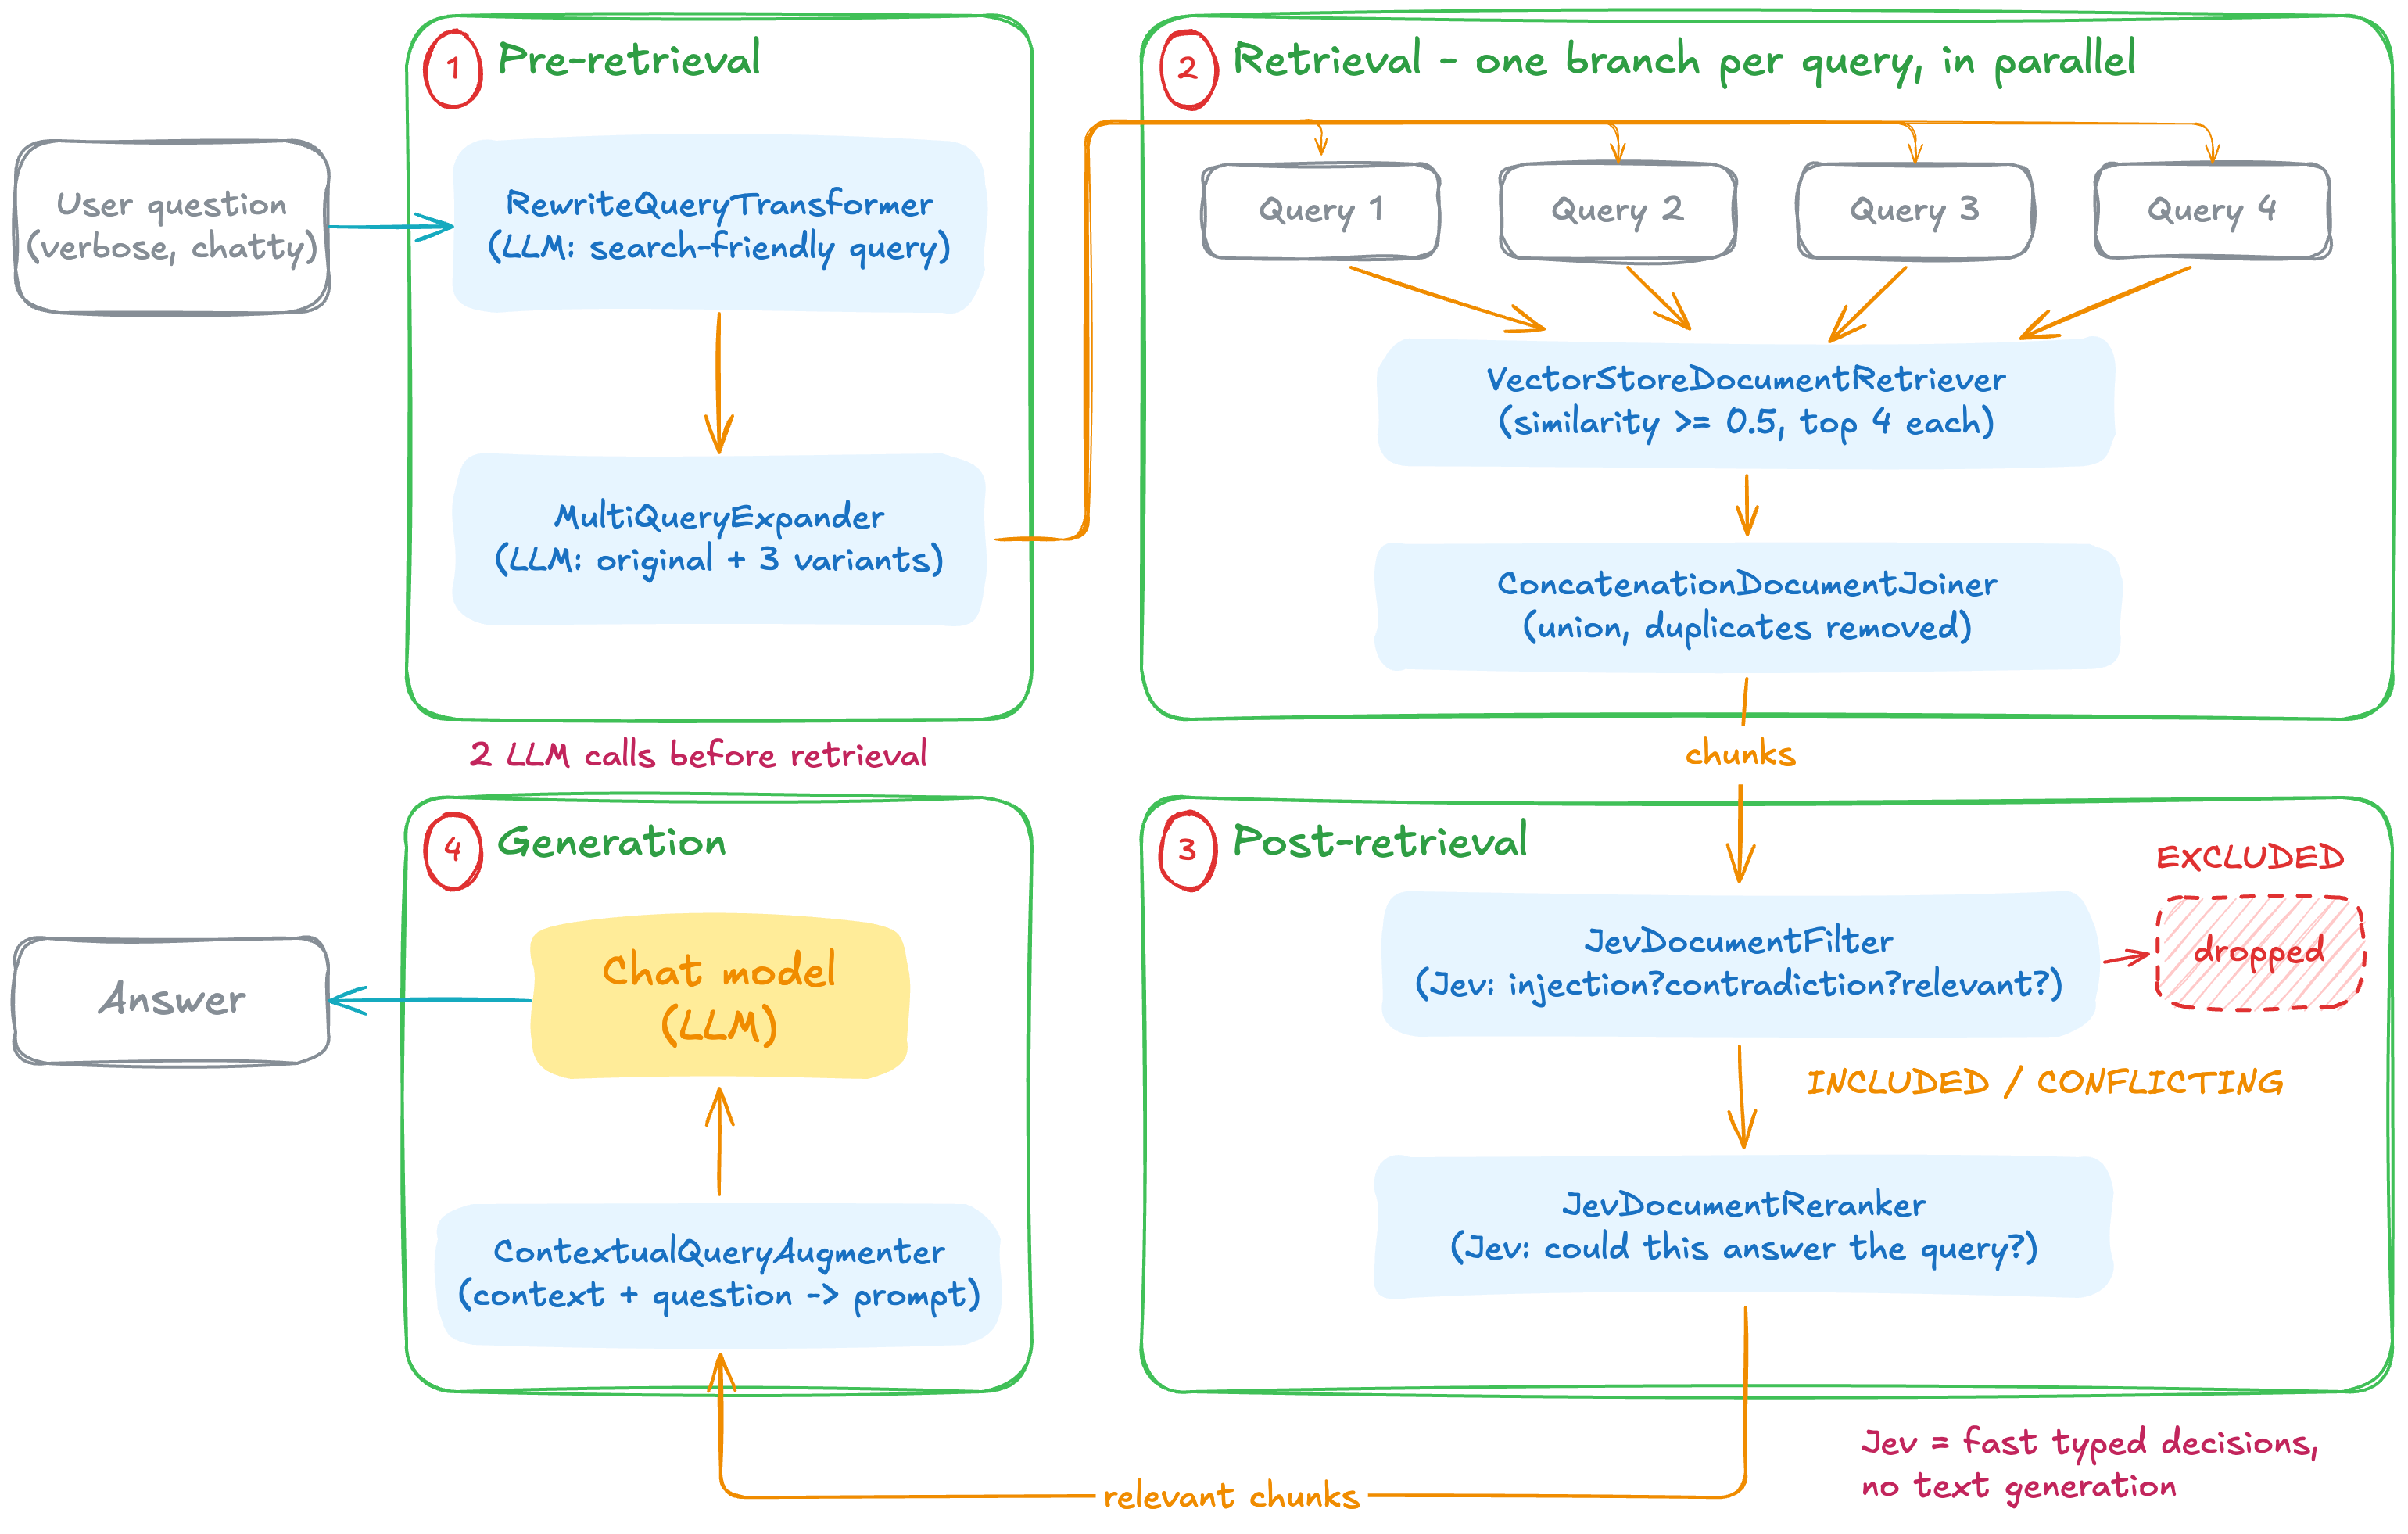
The retrieval branches run in parallel, one per query, and are joined before post-processing. Note one subtle detail: the post-processors and the augmenter see the user's original question, not the rewritten one. The rewrite only exists to improve search.
Getting Started
Add the Spring AI RAG module and the two TypeSafe artifacts from the previous article. Spring AI's BOM manages the first one:
<dependency>
<groupId>org.springframework.ai</groupId>
<artifactId>spring-ai-rag</artifactId>
</dependency>

<dependency>
<groupId>org.springaicommunity</groupId>
<artifactId>spring-ai-starter-typesafe</artifactId>
<version>0.3.0</version>
</dependency>

<dependency>
<groupId>org.springaicommunity</groupId>
<artifactId>typesafe-spring-ai</artifactId>
<version>0.3.0</version>
</dependency>
The starter auto-configures a TypeSafeClient bean from your API key:
spring.ai.typesafe.api-key=${TYPESAFE_API_KEY}The demo also uses spring-ai-pdf-document-reader for ingestion and spring-ai-starter-model-transformers for local embeddings.
The Pipeline
Ingestion is the same as in any Spring AI RAG application: read the PDF, split it into chunks, store them.
vectorStore.add(
TokenTextSplitter.builder().build().split(
new PagePdfDocumentReader(hurricaneDocs).read()));
The interesting part is a single builder. Each numbered comment is one brick from the diagram:
// Separate builder for the LLM-backed stages, so they don't inherit the main client's advisors
var ragClientBuilder = chatClientBuilder.clone();

var modularRag = RetrievalAugmentationAdvisor.builder()
// 1. Pre-retrieval: rewrite the chatty question into a search-friendly query
.queryTransformers(RewriteQueryTransformer.builder()
.chatClientBuilder(ragClientBuilder)
.build())
// 2. Pre-retrieval: expand it into several diverse queries (original included)
.queryExpander(MultiQueryExpander.builder()
.chatClientBuilder(ragClientBuilder)
.numberOfQueries(3)
.build())
// 3. Retrieval: similarity search per query; the default joiner dedups the union
.documentRetriever(VectorStoreDocumentRetriever.builder()
.vectorStore(vectorStore)
.similarityThreshold(0.5)
.topK(4)
.build())
// 4. Post-retrieval: Jev drops bad passages, then reranks and keeps the top 3
.documentPostProcessors(
JevDocumentFilter.builder(typeSafeClient).build(),
JevDocumentReranker.builder(typeSafeClient).topK(3).build())
// 5. Generation: stuff the surviving context into the prompt
.queryAugmenter(ContextualQueryAugmenter.builder()
.allowEmptyContext(true)
.build())
.taskExecutor(taskExecutor)   // see "Things to know" below
.build();
Using it looks like any other advisor:
String answer = chatClient.prompt()
.advisors(modularRag)
.user("I'm a Florida resident and heard a lot about storms last fall. "
+ "Did Milton actually make landfall in my state, and where?")
.call()
.content();
DocumentRetriever and DocumentPostProcessor are both single-method interfaces, so a lambda is enough to log what flows through the pipeline. The demo wraps the retriever and adds two printing post-processors around the Jev stages; that is where the output below comes from.
Jev in the Post-Retrieval Phase
Both components send one Jev call per passage, with the query and the passage as the state, and turn the answers into a decision.
JevDocumentFilter asks four Noul questions about every passage and applies them in order:
Question | Default threshold | Outcome |
|---|---|---|
| above | excluded |
| above | kept, tagged |
| below | excluded |
| above | kept, otherwise excluded |
This is the atomic questions idea from the previous article at work: four narrow questions, four thresholds, one call. Contradicting passages survive on purpose. If the user assumes something false, the model should see the evidence that says so. The classification is stored in the document metadata under jev.classification, and the thresholds are a Policy record you can override.
JevDocumentReranker asks a single question, could this passage answer the query?, sorts by the score and keeps the top K. The score lands in the metadata under jev.rerank.score. Its focus is deliberate: whether the passage states information that answers the query, not merely whether it covers the same subject. That is precisely the gap between similarity and usefulness.
Order matters. Filter first, so the reranker only pays for the survivors.
(节选)
原文:Spring Blog|Spring AI Modular RAG and TypeSafe Jev: Retrieve More, Keep Only What Answers,2026-10-02
成为第一条评论!
Nobody's responded to this post yet. Add your thoughts and get the conversation going.